
Should You Block AI Crawlers? GPTBot, ClaudeBot, and PerplexityBot for Merchants
For merchants, the question is no longer whether bots visit the store. It is whether each bot deserves the same access. AI crawlers can create visibility opportunities when an answer engine discovers, summarizes, or cites useful product and buying information. They can also raise concerns when they collect original guides, comparison content, pricing patterns, reviews, or other commercially valuable pages that took real investment to create.
So, should you block AI crawlers? The better answer is selective control, not a blanket yes or no. Allowing, limiting, or blocking access changes different things: allowing may support AI-answer visibility, limiting can protect high-value sections while keeping useful pages open, and blocking can reduce exposure where the crawler offers little business upside. That decision should be separate from eCommerce SEO choices involving traditional search crawlers, because protecting content from an AI crawler should not be treated as a shortcut for improving search rankings.
This guide separates GPTBot, ClaudeBot, and PerplexityBot instead of treating them as interchangeable. It also walks through the tradeoffs merchants actually face: content value, visibility goals, platform control, server-log evidence, and operational risk. The goal is a practical crawler policy that protects the store without cutting off channels that may still help customers find and trust the brand.
Should merchants block AI crawlers? The short answer
The decision should start with the page, not the bot name. A merchant with generic manufacturer descriptions has a different risk profile than a merchant with original buying guides, proprietary fitment data, category copy, customer reviews, dynamic pricing patterns, or inventory signals that competitors could learn from.
Use three practical buckets. Allow access where AI visibility may help shoppers discover or trust the brand, such as educational guides, public category pages, or evergreen product explainers. Limit access where the content is useful for discovery but commercially sensitive in bulk, such as comparison pages, review archives, or large product feeds. Block access where the crawler creates little upside, strains resources, or reaches content the business would not want reused outside the store experience.
That is why merchants should not block AI crawlers as a fear-based default. The better default is a selective policy shaped by five factors: how unique the content is, whether AI-answer visibility matters to the business, how much commercial risk the content carries, how much control the store platform provides, and whether the crawler follows the access rules you publish.
Keep this separate from online store SEO. This guide is about GPTBot, ClaudeBot, and PerplexityBot, not a broad instruction to block search engines. Treat AI-crawler access as a content and risk decision first, then make sure traditional eCommerce SEO crawlers remain governed by their own search-focused rules.
GPTBot, ClaudeBot, and PerplexityBot are not the same kind of crawler
In crawler policy, the user-agent string is the sorting mechanism. It tells your server, CDN, analytics tools, or bot-management layer which visitor is claiming to be Googlebot, Bingbot, GPTBot, ClaudeBot, PerplexityBot, an SEO audit tool, or something less transparent. That label matters because the commercial tradeoff changes with the crawler’s purpose.
- AI training crawlers collect public web content that may be used to improve or train AI systems. For merchants, the upside is usually indirect; the risk is that original buying guides, comparison copy, product explainers, or review language may become part of a broader model ecosystem rather than sending shoppers back to the store.
- Retrieval or answer-engine crawlers are more closely tied to generating current answers, citations, summaries, or shopping research experiences. Their potential value is visibility inside AI answers, but the tradeoff is that shoppers may receive summarized guidance before visiting the site.
- Traditional search crawlers, such as Googlebot or Bingbot, support search indexing and ranking systems. These should not be grouped with AI-specific crawlers when the goal is to protect content, because blocking them can interfere with ordinary search discovery.
- SEO audit crawlers are tools used by agencies, in-house teams, or vendors to inspect pages, links, status codes, metadata, and site structure. They can be useful during migrations, technical audits, and product page optimization, but they do not create consumer-facing search or AI visibility on their own.
- Malicious or low-quality scrapers often ignore robots.txt, rotate identities, copy pricing or inventory data, and consume server resources without a clear brand benefit. These belong in a different enforcement category than reputable crawlers that identify themselves and follow published access rules.
Robots.txt works best as a public access preference for cooperative crawlers, not as a security layer. A merchant might allow PerplexityBot on evergreen guides for answer visibility, disallow GPTBot from proprietary comparison hubs, and keep Googlebot fully allowed for search indexing. The mistake is treating every bot line as the same decision; the stronger approach is to block AI crawlers selectively when the user agent, page type, and business risk point in the same direction.
A practical decision framework for allowing, limiting, or blocking access
Turn the policy into a page-group decision: product pages, category pages, buying guides, comparison hubs, blog posts, reviews, and support content do not need the same rule. The useful test is whether AI access is more likely to create discovery value, expose commercially valuable work, reveal competitive signals, add operational load, or weaken brand control.
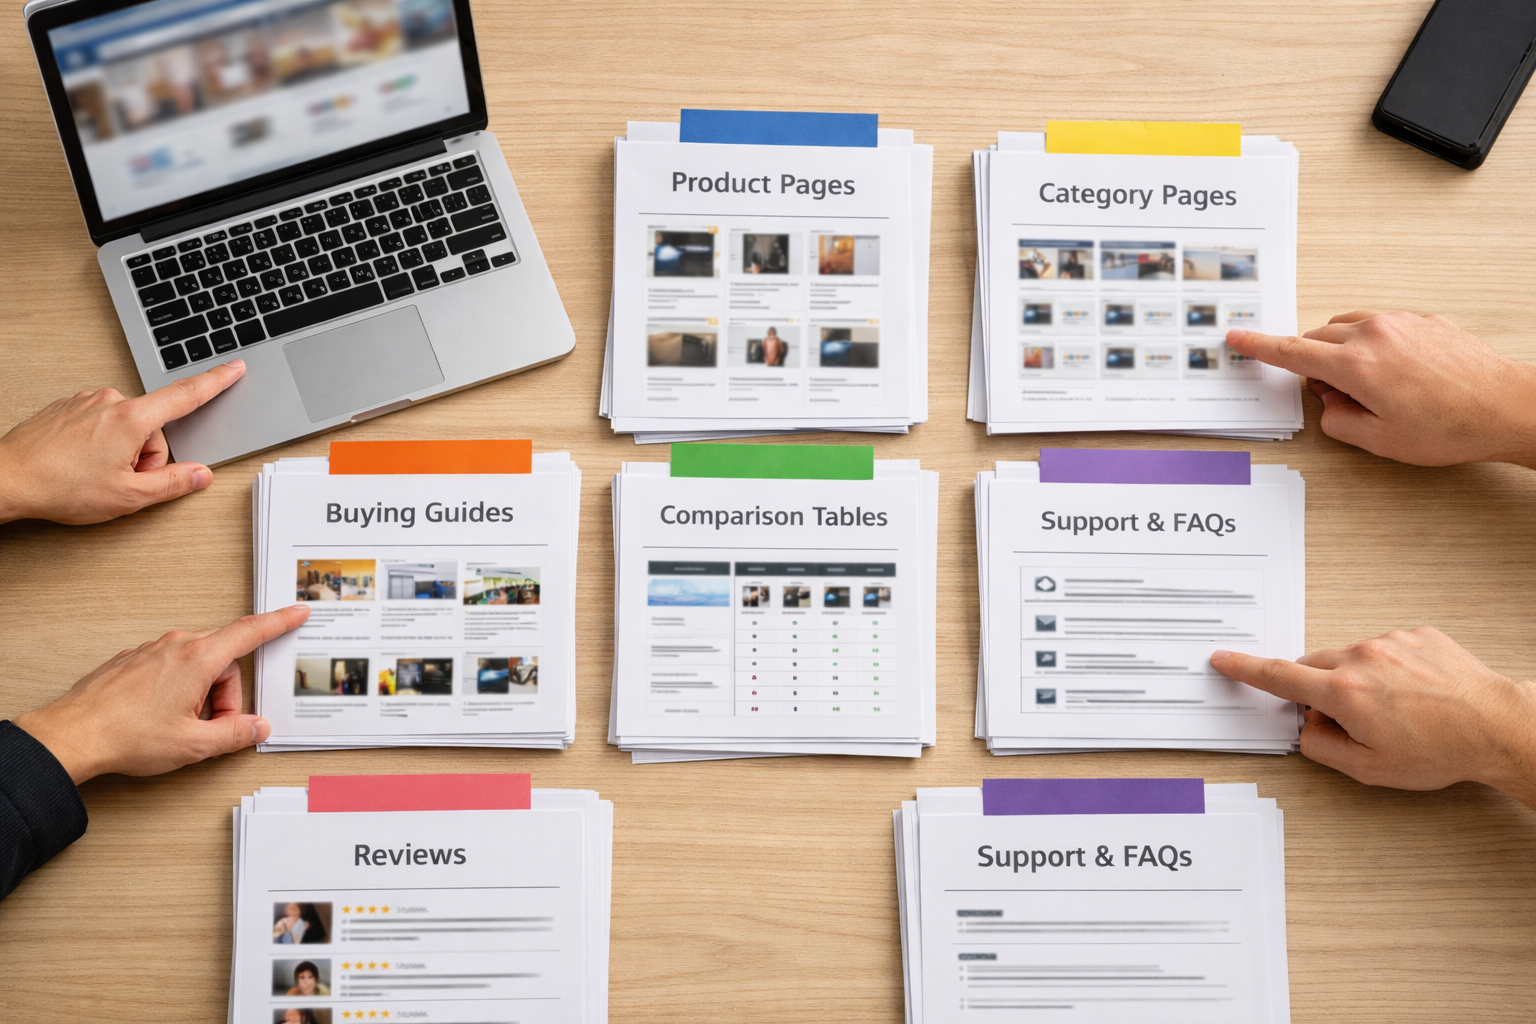
- Allow access when the store benefits from being found and summarized more than it needs to protect the underlying content. This fits merchants with commodity catalogs, reseller product pages built mostly from manufacturer copy, broad educational content, or a deliberate strategy to earn AI-answer visibility. A parts reseller, for example, may accept summaries of basic compatibility guidance if AI mentions can put the brand in front of shoppers earlier in the research journey. The practical takeaway: allow is a visibility-first choice, not a default permission for every page.
- Selectively limit access when different parts of the site have different commercial value. This is the strongest default for most merchants because it keeps useful discovery paths open while protecting high-investment assets. A private-label brand might allow AI crawlers on product pages and general care articles, but restrict original buying guides, comparison pages, fitment tools, review archives, or pages that expose pricing and inventory patterns. The practical takeaway: selective crawler access control lets you separate marketing content from proprietary content instead of treating the store as one uniform target.
- Block specific AI crawlers when a particular bot’s purpose does not match the merchant’s goals, or when the risk is concentrated in one use case. A luxury merchant with strict brand control may decide that AI-generated summaries of collection pages create more downside than referral value. A merchant with exclusive research, original editorial, or hard-won product data may block AI crawlers that are more associated with broad model improvement while allowing answer-oriented crawlers on lower-risk content. The practical takeaway: blocking AI crawlers should be bot-specific and page-specific whenever possible, not a blanket reaction.
Use weak and strong signals to avoid overcorrecting. Strong signals for restriction include original editorial content, proprietary product data, high brand-control requirements, aggressive competitor monitoring, unusual bot volume, or little evidence that AI surfaces are sending qualified shoppers. Weak signals include vague discomfort with AI, the assumption that every AI bot affects search rankings, or a desire to block everything before separating search crawlers from AI-specific user agents.
How blocking AI crawlers may affect SEO, search rankings, and AI visibility
The SEO risk usually comes from the rule you write, not from the AI bot you exclude. A rule aimed at GPTBot, ClaudeBot, or PerplexityBot is different from a rule aimed at Googlebot or Bingbot. Search crawlers discover, render, and refresh pages for traditional search indexes; AI-specific crawlers may support model training, answer generation, citation retrieval, or other AI product functions. If Googlebot and Bingbot can still crawl important product, category, and content pages, blocking selected AI crawlers should not be treated as a direct lever for changing search rankings.
The indirect tradeoff is visibility outside the classic search results page. If an answer engine can crawl or retrieve a useful buying guide, size chart, compatibility explanation, or category explainer, that content may have a better chance of being referenced, summarized, or cited in an AI answer. If you block access, you may reduce exposure in those surfaces while keeping traditional eCommerce SEO intact. That may be acceptable for proprietary comparison content, but less attractive for educational pages designed to introduce shoppers to the brand.
Referral traffic is the practical checkpoint. A merchant seeing qualified visits, assisted conversions, or brand searches after AI-answer exposure has a stronger reason to preserve some AI search visibility. A merchant seeing heavy bot activity with no measurable sessions, no branded demand lift, and no commercial value from AI mentions has a stronger case for restriction. The useful distinction is not “AI traffic good” or “AI traffic bad”; it is whether a specific crawler and page group produces value that justifies access.
Crawl-budget confusion is another reason to be precise. Merchants sometimes see bot volume in logs and assume every crawler competes with search indexing. The better question is which user agent is consuming resources and which pages it hits. A surge from an AI crawler on faceted filters, internal search pages, or low-value parameter URLs is an operational issue; a normal visit pattern from Googlebot to canonical product and category URLs is part of search maintenance.
The highest-risk mistake is editing robots.txt too broadly. A disallow rule written for “all bots” can catch search crawlers along with AI crawlers, which can damage discoverability in ordinary search. Keep search-engine rules separate from AI-crawler rules, test the exact user-agent targets, and review critical templates before publishing. For most merchants, the safest path is selective access: preserve search crawling, protect high-value content, and make AI visibility a deliberate business choice.
Content ownership, data sensitivity, and what robots.txt can actually do
Start with the assets that would hurt if they appeared in a competitor’s research workflow or an AI summary without your brand context. Examples include expert how-to articles, SKU-level product copy, comparison matrices, customer Q&A, reviews, pricing tests, and inventory-backed merchandising signals.
Use robots.txt for AI crawlers as a consent and preference layer for cooperative bots. An AI crawler robots.txt rule tells named crawlers which paths you do not want crawled, such as /guides/, /compare/, /reviews/, or internal search URLs. The practical tradeoff is clean: it is easy to publish, easy to audit, and appropriate for broad page-group rules, but it should not be treated as access control for confidential, regulated, or commercially sensitive data.
That distinction matters because robots.txt does not authenticate visitors, stop a noncompliant scraper, prevent someone from viewing public pages in a browser, or create a complete content licensing system by itself. If a page exposes sensitive pricing logic, supplier availability, private customer information, unpublished inventory patterns, or gated wholesale content, the answer is not simply “block AI crawlers.” The answer is to reduce public exposure and use stronger cybersecurity controls.
- Authentication requires a login before content is visible. It is the right control for dealer portals, wholesale pricing, account-specific catalogs, and private support material because the content is not publicly crawlable in the first place.
- Rate limiting slows repeated requests from the same source. It helps when bot activity is operationally heavy, but it does not decide whether a crawler is allowed to use the content.
- WAF rules and edge-level blocking act before traffic reaches the store application. They can block or challenge suspicious traffic by user agent, IP behavior, request pattern, geography, or other signals, which makes them stronger than a voluntary directive for abusive activity.
- Licensing terms define how content may be used. They are a business and legal control, not a crawler-control mechanism, so they should sit alongside technical restrictions when the content has independent commercial value.
The takeaway: use robots.txt to express selective access for compliant GPTBot, ClaudeBot, PerplexityBot, and similar crawlers, but do not rely on it to protect anything you would not willingly publish to the open web.
Use analytics and server logs before changing crawler policy
Before changing a rule, build a short evidence file from the traffic you already have. In server logs or CDN logs, isolate requests that claim GPTBot, ClaudeBot, PerplexityBot, or related AI user agents, then review the requested URL, IP, status code, response size, timestamp, crawl rate, and whether the visitor fetched /robots.txt. Those fields tell you whether the issue is content access, operational load, or simply a bot name appearing in reports.
Good signals look boring: a consistent user agent, predictable request spacing, mostly 200 and 304 responses, limited retries, and paths that resemble ordinary content discovery. Weak signals include sudden bursts from many unrelated IPs, repeated 404s, ignored disallow patterns, heavy requests to internal search, cart, checkout, account, faceted navigation, or parameter-heavy URLs, and crawls that spike bandwidth or slow page delivery during peak shopping hours.
- Bot reports group traffic by claimed crawler or behavior. Use them to separate known crawler labels from generic scrapers, but do not rely on the label alone.
- Analytics referrals show whether AI surfaces are sending shoppers, trial users, or low-quality visits. Compare AI referrals with organic traffic before and after any policy change.
- Crawl patterns show what the crawler values. Product and guide requests may support discovery; deep parameter loops usually create cost without merchandising benefit.
- Performance metrics reveal whether the crawler is a business problem. Track bot requests, bandwidth, cache hit rate, page speed, and origin load alongside revenue and lead quality.
The practical rule is simple: do not block AI crawlers because of one alarming visit. Restrict when the logs show repeated access to high-value or wasteful paths, allow when AI visibility appears useful and load is modest, and revisit the decision when retrieval-augmented generation referrals, bot volume, or content strategy changes.
How BigCommerce and Shopify merchants should implement crawler rules
Implementation should be narrow enough that the store’s search crawlers remain untouched. On BigCommerce, make the crawler policy part of the same release process you use for storefront files, SEO settings, CDN rules, and theme changes; that keeps BigCommerce SEO work separate from AI-crawler restrictions. On Shopify, the comparable storefront-level control is the theme’s robots rule layer, often handled through a robots.txt.liquid customization or an app-assisted workflow; that makes Shopify SEO risk mainly a targeting problem, not a reason to avoid AI-specific rules altogether.
The practical difference is control depth. A robots.txt rule is the lightest control: it tells cooperative crawlers what not to fetch, but it does not authenticate the visitor or stop noncompliant scraping. A CDN, WAF, or bot-management rule works earlier in the request path: it can rate-limit, challenge, or block traffic by user agent, IP pattern, behavior, path, or request volume. Use robots.txt for policy preferences; use edge controls when logs show load, abuse, ignored rules, or sensitive path probing.
A safe full-block pattern targets only the AI crawlers you intend to exclude and avoids a broad User-agent: * disallow:
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: PerplexityBot
Disallow: /

User-agent: Googlebot
Allow: /

User-agent: Bingbot
Allow: /
For a selective approach, block AI crawlers from high-value sections while leaving product and category discovery open:
User-agent: GPTBot
Disallow: /buying-guides/
Disallow: /compare/

User-agent: ClaudeBot
Disallow: /buying-guides/
Disallow: /compare/

User-agent: PerplexityBot
Allow: /
Disallow: /internal-search/
Disallow: /cart/
Disallow: /checkout/
Before publishing, use the final live URL paths, not placeholder paths from another platform. Then test the rendered /robots.txt, confirm that Googlebot and Bingbot are not caught by the AI rules, and monitor bot logs after deployment. If merchandising, SEO, and development teams all touch the storefront, assign one owner for the crawler file so an app update, theme deployment, or edge rule does not silently reverse the policy.
Recommended policy: start selective, document the reason, and revisit it
Add an owner and review date to the crawler change before it ships. Make the policy a short internal decision record, not a one-time robots.txt edit: for GPTBot, ClaudeBot, and PerplexityBot, record the user agent targeted, page groups affected, business reason, expected upside or risk, and review date. “Allow” means the crawler can reach ordinary public content where citation, discovery, or AI search visibility may help. “Block” means excluding a specific bot from the whole store because the risk or load outweighs the value. “Restrict” means drawing a boundary around assets such as expert editorial pages, comparison tables, internal search, cart, checkout, or proprietary support content while leaving lower-risk pages available.
Escalate beyond robots.txt when the issue is not preference but behavior: repeated high-volume requests, ignored disallow rules, path probing, or performance pressure. In that case, use CDN, WAF, rate-limit, or bot-management controls that can act before the request reaches the storefront.
The recommended default for most merchants is selective access: do not block AI crawlers indiscriminately, do protect high-value commercial content, keep search-crawler rules separate, and revisit the policy after measurable triggers such as traffic shifts, new AI referrals, crawler policy changes, site-performance issues, or a major catalog strategy change.
The practical takeaway for merchants
The finished policy should be usable by marketing, merchandising, and development, not just whoever edits robots.txt. Marketing needs to know which AI surfaces the brand is willing to appear in. Merchandising needs to identify pages where product copy, comparisons, reviews, pricing logic, or buying advice create competitive value. Development needs enough specificity to target the right user agents and paths without sweeping search crawlers into the same rule.
Use a simple scorecard before you block AI crawlers: public product and category pages with modest risk can remain open; original guides, comparison hubs, and proprietary support content may deserve restrictions; abusive or wasteful crawl patterns should move from preference rules to stronger traffic controls. That distinction keeps the decision tied to business value instead of fear, hype, or a single bot report.
For most merchants, the durable answer is not “allow everything” or “block everything.” It is a documented, selective policy for GPTBot, ClaudeBot, PerplexityBot, and search crawlers separately, implemented carefully on whichever platform manages the storefront, whether that is BigCommerce, Shopify, or another stack.
After publishing the rules, monitor crawl logs, AI referrals, organic search performance, server load, and affected page groups. Revisit the policy on a set schedule and after major changes in crawler behavior, AI search experiences, catalog strategy, or platform controls. The right crawler policy is a living operating decision, not a permanent one-line disallow.