
AI Share of Voice: How to Measure Your Brand’s Visibility in AI Answers
When a buyer asks an AI tool to compare vendors, summarize a category, explain tradeoffs, or build a shortlist, the brand outcome is no longer limited to “did we rank?” The answer may name your company, cite your content, recommend a competitor, describe you inaccurately, or leave you out entirely. Those are different visibility events, and they need to be measured differently.
AI share of voice is a way to quantify your brand’s relative presence inside AI-generated answers for a defined set of commercially important prompts. It is not just AI search visibility, SEO ranking, media mentions, or referral traffic under a new label. The practical question is narrower and more useful: when prospective customers ask AI systems about problems you solve, categories you compete in, and vendors they should consider, how often does your brand appear, how prominently, in what role, and against which competitors?
This matters because answer-based discovery compresses the journey. A buyer may not click ten blue links before forming an opinion; the summary itself can shape the shortlist. That makes brand visibility in AI answers a measurable business signal, even if it is not perfectly deterministic.
The framework in this article is designed for repeatable measurement, not false precision. AI outputs can vary by platform, model version, prompt wording, retrieval behavior, location, personalization, and time. The goal is to build a defensible view of visibility patterns across tools such as ChatGPT, Gemini, Perplexity, Claude, Copilot, and AI search experiences, not to claim a universal score that captures every possible answer.
What AI share of voice actually measures
The cleanest unit of measurement is a single prompt-platform-answer instance: one prompt, run on one AI surface, captured as one answer at one point in time. AI share of voice, a way of monitoring what AI systems say about your brand, is then calculated from many of those instances using rules you define in advance: which prompts count, which platforms count, which competitors are included, and how each answer is scored.
- Mention presence records whether the brand appears at all. A named mention is stronger than omission, but it does not tell you whether the answer helped or hurt the brand.
- Prominence captures where and how the brand appears. Being named first in a shortlist, included in a summary table, or described in the opening recommendation carries more weight than a passing reference near the end.
- Recommendation status separates neutral inclusion from active endorsement. “Consider Brand A for mid-market teams” is a stronger signal than “Brand A is one of several vendors in this space.”
- Citations track whether the AI answer uses your owned content, third-party profiles, reviews, articles, or competitor pages as supporting material. A brand can be mentioned without being cited, cited without being recommended, or absent while competitors receive source attribution.
- Sentiment describes the framing: positive, neutral, mixed, or negative. A negative mention may increase raw visibility while weakening commercial perception.
- Competitive context compares your presence with named rivals, substitutes, publishers, marketplaces, and category authorities. The useful question is not only “were we visible?” but “who shaped the answer instead?”
Treat the result as directional and comparative. It is not an official industry-standard replacement for traffic, revenue attribution, SEO visibility, PR share of voice, or brand tracking. Its value is in showing patterns in AI answer visibility across a controlled sample, while leaving room for variation by prompt wording, account context, location, settings, freshness, retrieval behavior, and time.
How AI visibility differs from traditional search rankings
A search result is a list of destinations; an AI answer is a synthesized response that may collapse those destinations into a recommendation, comparison, or summary. That changes what you measure. In traditional search rankings, the core unit is usually a URL’s position for a query. In AI visibility, the core event is whether the answer uses the brand, source, or competitor in a meaningful role.
Source attribution also works differently. A citation is a linked or named source used to support the answer. A mention is the brand appearing in the text. A recommendation is stronger: the system actively suggests the brand as a fit for a need, budget, use case, or category. A company can earn a citation without being recommended, be mentioned without a citation, or be excluded while a competitor is framed as the best option.
That is why strong SEO can influence AI visibility but does not make it automatic. A page ranking first in organic search for “best enterprise CRM for manufacturers” may still be absent from an AI-generated shortlist if the answer favors review sites, analyst-style summaries, fresher sources, different wording, or a narrower interpretation of the prompt. Treat AI search rankings as related signals, not a simple extension of rank tracking.
The practical takeaway for answer engine optimization is to measure the answer itself: the wording, cited sources, brand role, competitor role, and repeatability across prompts and sessions. Visibility is not just position; it is inclusion, framing, and influence inside the generated response.
Step 1: Build a prompt set that reflects real buying questions
Start by deciding which buyer questions deserve to be in the sample, because the prompt set determines what your AI share of voice can and cannot reveal. A defensible set should be specific enough to reflect commercial demand, but not so narrow that it only tests whether an AI system recognizes your branded language.
Group the sample by intent so you can see where visibility appears or disappears across the buying journey:
- Educational: questions that define the category or explain a concept, such as “what is revenue intelligence software?” These show whether your brand is associated with category understanding.
- Category comparison: prompts like “best tools for revenue forecasting for mid-market SaaS companies.” These test whether the answer includes your brand when the buyer is still forming a shortlist.
- Problem-solution: questions such as “what should I use to reduce manual sales forecasting errors?” These reveal whether the system connects your brand to a specific pain point.
- Vendor shortlist: prompts such as “recommend vendors for enterprise contract management.” These are closer to purchase intent and should carry more weight in scoring.
- Implementation: questions about setup, migration, integrations, onboarding, or internal adoption. These show whether your brand is framed as practical to deploy, not just known.
- Pricing: questions about cost, plans, budget fit, or total cost of ownership. These often surface buyer objections and competitor comparisons.
- Alternatives: prompts like “compare Salesforce alternatives for small B2B teams.” These capture substitution behavior, including cases where your brand should appear even if the buyer starts with another vendor.
- Risk evaluation: questions about limitations, reliability, support, security, or who a product is not right for. These help you measure negative or cautious framing.
Strong queries sound like something a real buyer would ask: “compare Asana alternatives for a 50-person marketing team,” “best tools for HIPAA-compliant customer support,” or “what should I use for multi-location inventory management?” Weak tests include one-word category terms, prompts that only ask about your brand, or artificial phrasing no prospect would use.
Include both competitor-neutral and competitor-comparison wording. Neutral wording measures category discovery; comparison wording measures whether you appear when a buyer is already evaluating named options. Keep the list stable for each reporting period so changes in visibility reflect answer behavior, not a constantly shifting measurement sample.
Step 2: Choose AI platforms and set sampling rules
Choose the platforms after you know whose behavior you are trying to approximate. A B2B software company may prioritize ChatGPT, Claude, Copilot, and Perplexity if its buyers use workplace assistants and AI search tools for research. A consumer brand may add Gemini and Google AI Overviews because discovery may happen closer to search. The practical decision is not “which AI tool matters most?” but “which answer surfaces could plausibly influence this audience, in this market, for these prompts?”
Treat each platform as a separate measurement environment, not an interchangeable interface. A conversational assistant may produce a synthesized answer without visible sources; an AI search surface may emphasize citations; a search-results enhancement may appear only for some queries, users, or locations. Those differences change what you can score. If citations are not shown, score the answer text and brand role. If citations are shown, capture both the cited domains and the generated wording.
- Runs per prompt: use at least three runs per prompt-platform pair when practical. One run is a screenshot; repeated runs show whether the brand appears consistently or only sporadically.
- Timing: run the sample on the same day or in the same reporting window, then repeat monthly or quarterly. Avoid mixing launch-week tests with routine monitoring unless you label them separately.
- Location: record country, region, and language. Geography can affect availability, retrieval, local recommendations, and brand relevance.
- Account and browser state: note whether the test used a logged-in account, a fresh browser, previous chat history, extensions, or personalization. Keep the state consistent across competitors.
- Model or product version: capture the model name, product mode, or answer surface when visible. If the interface does not expose a version, record the product name and date.
- Citation setting: specify whether web access, browsing, search, or citations were enabled. This separates closed-answer visibility from retrieval-influenced visibility.
Your spreadsheet should therefore include: platform, prompt, run number, date, location, login state, browser state, visible model or mode, citation setting, full answer text, cited URLs or domains, and competitors mentioned. That structure makes AI share of voice easier to defend because every score traces back to a captured answer, not a memory of what the tool seemed to say.
Step 3: Score mentions, citations, recommendations, and sentiment
Turn each captured answer into a row of scores before you calculate totals. The goal is not to pretend the answer is perfectly measurable; it is to make your judgment consistent enough that the same answer would receive the same score next month.
| Dimension | What to score | Simple scoring option |
|---|---|---|
| Presence | Whether the brand appears in the generated answer. | 0 = absent, 1 = mentioned, 2 = cited or sourced, 3 = recommended or shortlisted. |
| Prominence | Where and how strongly the brand appears. | 1.0 = lead recommendation, 0.75 = included in main list, 0.5 = brief mention, 0.25 = footnote or passing reference. |
| Role | What the answer uses the brand for. | Recommended vendor, example, cited publisher, comparison target, excluded option, or warning. |
| Citations | Whether the answer attributes support to your site or a third-party page about you. | Give full credit for your owned domain, partial credit for credible third-party attribution, and no citation credit when only competitors or publishers are cited. |
| Sentiment | Whether the framing helps or hurts consideration. | 1.2 = positive, 1.0 = neutral, 0.7 = mixed, 0.3 = negative or cautionary. |
| Competitor relationship | How your brand appears relative to alternatives. | Add a note such as “ranked above Competitor A,” “listed after Competitor B,” “recommended instead of us,” or “category leader cited, brand absent.” |
A practical row-level score is: base presence score × prominence modifier × sentiment modifier × prompt weight × platform weight. For AI share of voice measurement, calculate the overall percentage as: your total weighted score ÷ total weighted score for all tracked brands. Keep separate views for mention share, recommendation share, citation share, and sentiment-weighted visibility so one strong metric does not hide a weak one.
Weight prompts by business value. A “best vendor for enterprise migration” prompt may deserve more weight than a broad educational prompt because it is closer to selection. Weight platforms only if you have a clear reason, such as audience usage or market importance. Do not blend citation-heavy AI answer tracking with non-citation answer tracking unless the dashboard shows the weighting rules; otherwise, changes in citations can look like changes in brand demand.
Step 4: Benchmark competitors and interpret the pattern
Competitor benchmarking should include every entity that can take attention away from your brand, not just companies that sell the same product. Direct competitors show vendor-to-vendor visibility. Substitutes show whether AI answers recommend a different way to solve the problem. Marketplaces reveal whether the answer sends buyers to an aggregator instead of a brand. Publishers, review sites, and category authorities show which information sources shape the answer even when they are not sellers.
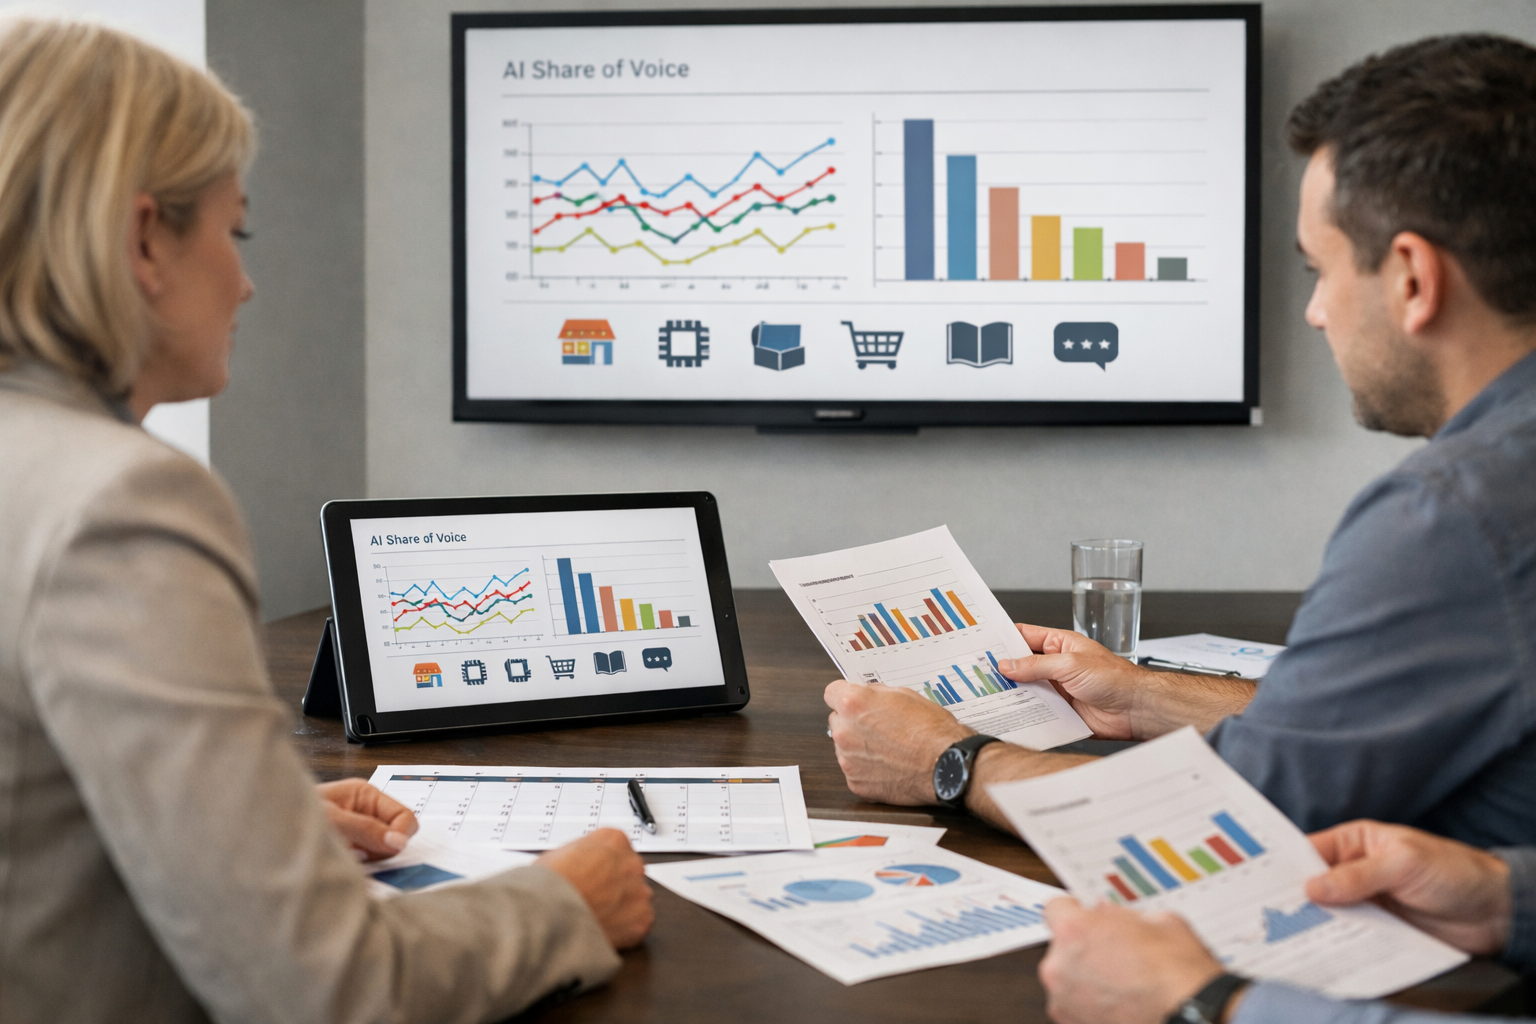
Build the comparison table by prompt cluster and multiple discovery platforms, then read the pattern before averaging the score. If your brand appears often but is rarely cited, the model may recognize the name without treating your site as a supporting source. If your content is cited frequently but the brand is not recommended, you may be influencing the answer while losing the commercial shortlist. If sentiment is positive but prominence is weak, the brand may be framed well but buried behind stronger competitors. If visibility is strong in educational prompts and weak in “best,” “compare,” or “shortlist” prompts, the gap is likely closer to positioning than awareness.
A good AI share of voice result is therefore relative, not universal. A 20% score may be strong in a fragmented category with many credible alternatives and weak in a mature category where three vendors dominate. Interpret the number against the competitive set, prompt mix, and platform behavior: who is named first, who is cited, who is recommended, and which answer types consistently exclude you.
Step 5: Report trends without overstating precision
Reporting should make the pattern easier to act on, not make the number look more exact than the underlying sample allows. For most brands, a monthly or quarterly cadence is enough to show movement in AI share of voice without reacting to every answer fluctuation. Move to weekly or campaign-level checks when the market is changing quickly: a product launch, pricing change, reputation issue, analyst report, major content push, or competitor announcement.
Show confidence signals beside the score. Useful signals include the number of prompts tested, platforms covered, repeat runs per prompt, percentage of answers with citations, and how many answers changed materially from the last period. A stronger report says, “visibility improved across 18 of 40 commercial prompts, especially in comparison prompts on Perplexity and Gemini.” A weaker report says, “we are up 3.7%,” without showing whether that shift came from one volatile prompt or a broad pattern.
Keep an audit trail for AI brand monitoring and AI answer tracking: prompt, date, platform, full answer, citation URLs, brand score, competitor score, and analyst notes. Report bands, trends, and directional movement, gaining, flat, declining, rather than pretending large language model visibility can be reduced to a permanent decimal-point ranking.
How to improve visibility in AI-generated answers
Low-scoring prompt clusters should become an action backlog, not just a reporting note. Start with entity clarity: make the brand name, category, products, use cases, industries served, locations, leadership, and differentiators consistent across the places you control. If an answer misclassifies you, the fix is often clearer positioning language, not more keyword repetition.
- Strengthen authoritative pages: publish pages that directly answer buyer questions, explain tradeoffs, define ideal-fit and poor-fit scenarios, and keep dated claims current.
- Fill comparison gaps: create fair alternative, competitor, and category pages so AI systems have source material that explains how options differ instead of relying only on third-party summaries.
- Improve structured information: use consistent names, schema where appropriate, clear tables, pricing or packaging explanations, and crawlable text that is easy to extract and summarize.
- Earn validation beyond your site: digital PR, review presence, analyst coverage, partner pages, industry publications, forums, and news mentions can all reinforce whether your brand appears credible in a category.
- Maintain SEO foundations: crawlability, internal linking, page quality, and eCommerce SEO basics still matter, but AI search optimization and answer engine optimization should be judged by answer inclusion, not rankings alone.
Case-study content is a useful model when it includes client background, challenges, solutions, and implementation details, because it gives both buyers and summarization systems concrete context instead of vague proof points.
Finally, keep AI visibility in its proper role. Use it alongside traffic, conversions, revenue, sales feedback, reviews, and brand health metrics so the team improves market presence, not just the appearance of presence inside generated answers.
Make AI visibility measurable before trying to improve it
The most useful next step is operational discipline: decide the measurement rules before the team debates tactics. A prompt set defines which buyer questions count. A platform list defines where visibility is being sampled. Scoring rules define what counts as a weak mention, strong recommendation, citation, favorable framing, or absence. The competitor set defines who can win attention instead of you. The reporting cadence defines whether the team is looking for trend movement or reacting to noise.
That structure turns AI visibility from a one-time audit into a repeatable workflow. A strong signal is not one flattering answer; it is repeated inclusion across commercially important prompts, relevant tools, and competitor comparisons. A weak signal is a brand that appears only when prompted by name, is omitted from category shortlists, or is described with outdated positioning. For teams already investing in organic visibility, including online store SEO programs, this gives a complementary view: not just whether pages rank, but whether AI-generated answers understand, cite, and recommend the brand in the contexts that matter.
The final takeaway: treat AI share of voice as a directional visibility metric, not a perfect scorecard. Use it to guide better content, clearer positioning, stronger third-party validation, and more durable authority signals over time.