
Faceted Navigation SEO: How to Stop Filters From Killing Your Rankings
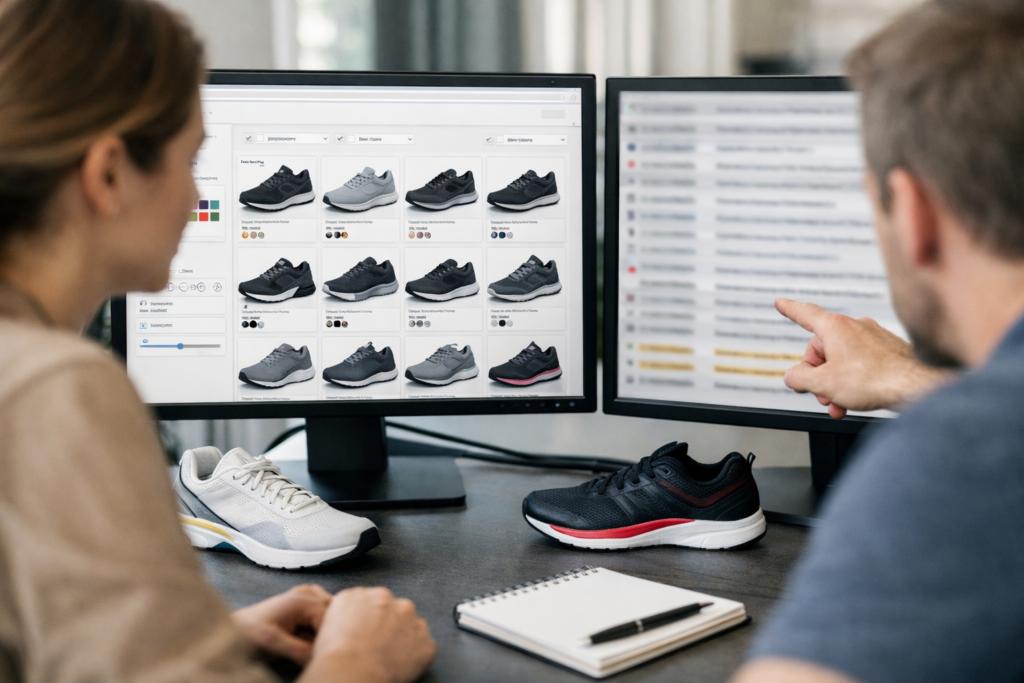
Faceted navigation is one of the most useful parts of an ecommerce category page because it lets shoppers narrow a broad product set by attributes such as brand, size, color, price, sort order, availability, and ratings. The same feature that helps a customer move from “men’s shoes” to “Nike men’s running shoes in size 10” can also create a new URL every time a filter is applied.
That is where faceted navigation SEO becomes a technical problem. A single category with 10 brands, 8 sizes, 12 colors, 5 price ranges, 4 rating choices, and multiple sort options can produce hundreds or thousands of URL combinations. Some combinations may represent real search demand and deserve a strong landing page. Others are near-duplicates, thin variations, or temporary views that do not help search engines understand which page should rank.
The risk is not that filters exist. The risk is letting every filtered state compete for crawling, indexing, links, and relevance signals as if it were a distinct page. Left unmanaged, filter URLs can waste crawl activity, inflate the index with low-value pages, create duplicate titles and metadata, and dilute authority across many versions of the same category.
The practical goal is to keep the shopping experience intact while deciding which filtered URLs should be discoverable, indexable, internally linked, and included in sitemaps, and which should be controlled. That decision framework is central to eCommerce SEO because it protects search rankings without removing the filters customers rely on to buy.
How Filtered URLs Damage Organic Performance
The damage usually shows up in search data before it shows up in rankings: more discovered URLs, more duplicate clusters, more low-value crawls, and fewer clear signals about the page that should own the category query.
A crawl trap happens when filters keep generating new paths for bots to follow. A shopper may only apply one or two refinements, but a crawler can encounter endless combinations such as ?color=black&size=10&brand=nike&price=50-100&sort=price-desc. Sort options, price sliders, rating filters, and availability toggles are especially risky because they often change the order or subset of products without creating a meaningfully different search landing page. The practical tradeoff is crawl budget: time spent on weak combinations is time not spent discovering new products, refreshed categories, or stronger commercial pages.
Duplicate category pages are the next failure point. If “running shoes,” “running shoes sorted by newest,” and “running shoes under $200 sorted by price” all use similar titles, headings, product grids, and descriptions, search engines may treat them as overlapping versions of the same page. Parameterized URLs make this worse when the same filtered state can be reached through multiple URL orders, such as ?brand=nike&color=black and ?color=black&brand=nike. The page may look harmless to users, but the index sees competing URLs with unclear priority.
Thin filtered pages create a different problem. A filter combination with two products, no unique copy, no distinct metadata, and no search demand does not add much value as a search result. A strong filtered page usually aligns with a recognizable query, has enough inventory, and deserves a distinct title and internal links. A weak one is just a temporary product view.
Ranking signal dilution follows from that confusion. Internal links, external links, canonical hints, breadcrumbs, and sitemap inclusion may point to different versions of the same category. Instead of reinforcing one authoritative page, the site spreads relevance across many near-identical choices.
Index bloat is the visible outcome: large numbers of filtered URLs appearing in Google Search Console as “Crawled – currently not indexed,” “Discovered – currently not indexed,” or “Duplicate without user-selected canonical.” Those reports are not automatically bad, but at scale they are a warning that URL generation and indexation rules are not aligned.
The filter interface is not the enemy. The problem is letting every possible state become a crawlable, indexable candidate without deciding whether it serves a distinct search intent.
Start With a Filter URL Audit, Not a Blanket Rule
Before choosing controls, build an inventory that shows how the store actually generates filter URLs. A site crawl gives you the visible path through category links, filter links, pagination, canonicals, titles, meta descriptions, status codes, and internal link counts. Export indexed or indexable URLs from Google Search Console, then compare them with crawl data, XML sitemaps, analytics landing pages, and, where available, server logs that show how often search bots request each pattern.
Group every pattern by URL structure. Query-string filters use URL parameters, such as ?brand=nike&color=black; path-based filters place the selection in the folder structure, such as /running-shoes/nike/black/; hash fragments use #color=black, which may not represent a normal crawlable URL state; combined attributes stack multiple refinements into one address. The practical takeaway is that each format changes how easily crawlers discover, cluster, and revisit those pages.
Then classify the filters by what they change. Brand, gender, size, color, material, product type, price, rating, availability, and sort order are not equal. A brand-plus-category page may match real search demand and deserve evaluation as a landing page. A sort option usually rearranges the same products. A price slider may generate too many unstable ranges. An availability toggle can change frequently and produce weak pages. This distinction is the foundation of faceted URLs SEO work.
For each group, capture the decision metrics: indexed status, clicks, impressions, product count, canonical target, number of internal links, crawl frequency, title/meta duplication, and whether the page matches a clear query intent. A strong audit row looks like “/women/dresses/black/, 240 products, impressions, unique title, linked from category copy.” A weak row looks like “?price=37-42&sort=newest, 6 products, no impressions, duplicate title, crawler hits.” Faceted navigation SEO decisions should come from that contrast, not from a sitewide rule applied to every filter.
Decide Which Filtered Pages Should Be Indexed
Treat the audit rows as candidates, not verdicts. A filtered URL earns indexation only when it can act like a useful search landing page, not merely because the filter exists. The strongest candidates usually combine a broad category with a commercially meaningful refinement: brand, gender, product type, material, compatibility, or occasion. “Nike running shoes,” “women’s leather boots,” “USB-C laptop chargers,” and “wedding guest dresses” can represent distinct intent, distinct merchandising, and enough search demand to justify long-tail landing pages.
The first decision criterion is demand, grounded in shopper intent. Search demand means people use language that matches the filtered page closely enough for the URL to satisfy a query on its own. Brand-plus-category pages often work because shoppers search that way. High-demand materials, use cases, and compatibility filters can also work because they narrow the problem the buyer is trying to solve. By contrast, sort order, view count, and session IDs do not express search intent; they change the browsing state, not the topic of the page.
The second criterion is uniqueness. A page should have its own title, H1, introductory copy, product set, and merchandising angle. If “black dresses” and “black cocktail dresses” show nearly the same products with the same metadata, indexing both can split signals instead of strengthening category page SEO. If the narrower page has a clearly different product set and copy that explains the selection, it becomes a stronger candidate for SEO for filtered category pages.
Inventory depth is the next checkpoint. A filter combination with two products today and zero next week is usually too fragile to index. Stable inventory gives the page a better chance to satisfy shoppers and avoids creating thin or empty landing pages. Enough products does not mean a universal number; it means the page looks complete for the query, supports comparison, and is unlikely to collapse whenever stock changes.
Intent and conversion value should narrow the list further. “Waterproof hiking backpacks” suggests a shopper with a defined need; “rating: four stars and up” is usually a preference layered on top of another journey. Price sliders, availability toggles, and ratings-only filters can help users refine results, but they rarely create a durable search topic. Excessive multi-select combinations, such as brand plus color plus size plus price plus rating, usually become too specific to attract meaningful demand.
Finally, ask whether the page deserves internal links. If a filtered page is important enough to index, it should be important enough to link from relevant category copy, navigation modules, buying guides, or curated collections. That internal linking value is a useful forcing function: it separates strategic long-tail landing pages from filter noise that should remain available to shoppers without competing in search.
Use Canonical, Noindex, Robots.txt, and Internal Links for Different Jobs
The control you choose should match the failure mode in the URL pattern. A URL that deserves to rank needs a different treatment from a URL that only changes sorting, tracking, price boundaries, or temporary stock state.
Canonical tags are best for near-duplicate pages where the page can remain crawlable but should consolidate signals into a preferred URL. If /women/dresses?color=black is just a duplicate rendering of a curated /women/dresses/black/ page, the parameter URL should canonicalize to the clean landing page. If a filter produces no distinct search value, such as /women/dresses?availability=in-stock, the canonical target is usually the parent category. The tradeoff: canonicalization still allows crawling, so it reduces duplication signals but does not fully stop crawl waste.
Noindex tags fit pages users may need but search results do not. A filtered page with useful on-site function but weak search value can remain accessible to shoppers while telling search engines not to keep it in the index. That makes noindex useful for low-value combinations, thin filtered states, and empty or near-empty result pages that should not compete with core categories. The important limitation is that search engines need crawl access to see the directive; if the same URL is blocked before it can be crawled, the noindex instruction may never be processed.
Robots.txt is a crawl-access control, not an index-quality tool. It is appropriate when a URL pattern creates an effectively endless crawl space or contains non-content parameters that do not need to be fetched at all, such as session IDs, internal tracking parameters, repeated sort states, or calendar-like combinations. It is risky for pages that rely on canonical or noindex signals because blocking access can prevent search engines from seeing those page-level directives. Use it to reduce obvious crawl traps, not as a blanket substitute for indexation strategy.
- Indexable landing page: allow crawling, self-canonicalize, include in relevant internal links, and consider sitemap inclusion only when it is a stable SEO landing page.
- Duplicate filter: allow crawling and canonicalize to the clean preferred page, either the filtered landing page or the parent category.
- Sort parameter: usually keep out of the index with canonicalization to the unsorted category; block only if it creates excessive crawl paths.
- Price range or slider: usually noindex or canonicalize unless the range maps to real search demand, such as a curated “under $100” page.
- Session or tracking parameter: remove from internal links where possible and consider robots.txt blocking because it does not represent content.
- Empty result page: noindex, avoid internal promotion, and route users to adjacent useful categories instead of letting the URL become a search landing page.
Internal links are the priority layer. Search engines discover and value pages partly through the links a site chooses to expose. Strategic faceted navigation SEO therefore does not depend on tags alone: indexable filters should receive deliberate links, while low-value states should be available through the interface without being promoted as important destinations.
Turn Valuable Filter Combinations Into Real Landing Pages
For the filtered pages you deliberately promote, the URL should stop looking like a temporary interface state and start behaving like a curated category asset. A weak version is /dresses?color=black&size=m&sort=price-asc: it mixes a valuable attribute with a shopper preference and gives search engines little reason to treat it as a distinct destination. A stronger version is /women/dresses/black/, self-canonicalized, internally linked, and built around the intent behind “black dresses for women.”
Clean URLs matter because they define the preferred page in a form that is easier to link to, measure, merchandise, and keep stable. Parameter URLs are useful for interface states; curated paths are better for filtered category pages that target persistent demand. The practical takeaway: reserve clean, indexable URLs for combinations you are willing to maintain like categories, not for every possible filter state.
Build each selected page with unique metadata and a descriptive heading that matches intent without repeating keywords mechanically. For example, use a title such as “Black Dresses for Women | Cocktail, Casual & Formal Styles” and an H1 such as “Black Dresses for Women,” rather than “Dresses – Black – Size Medium – Sort By Newest.” Good ecommerce filter SEO makes the refinement clear, but avoids turning metadata into a list of applied filters.
Add a short intro that helps the shopper choose, not a generic paragraph pasted across every variation. Mention the attribute’s buying context, major subtypes, materials, fit considerations, or use cases when those details are genuinely relevant. If the page targets long-tail keywords, the copy should answer the intent behind them while still letting the product grid remain the main experience.
- Product depth: set a minimum merchandising threshold before indexation; for many catalogs, expect roughly 20â30 relevant products as a practical floor, with higher thresholds for broad competitive queries.
- Stable grid: avoid indexable pages that frequently collapse to a handful of products, out-of-stock items, or near-empty results.
- Crawlable links: link to the page from relevant parent categories, collection modules, buying guides, or footer/category navigation where the destination is genuinely important.
- Schema: use structured data where it accurately describes the page, such as breadcrumbs and item lists; do not force product-level markup onto a page that is not a single product detail page.
Finally, prevent overlap. A filtered page should not compete with the parent category for the same broad query or with a product page for a specific SKU query. Its job is to own a distinct middle layer: specific enough to satisfy long-tail keywords, broad enough to offer meaningful choice.
BigCommerce and Shopify Considerations for Faceted Navigation
Platform rules determine how much of your faceted navigation SEO plan can be handled in settings, how much belongs in the theme, and how much needs developer-level SEO work. On BigCommerce, start with category and product filtering behavior, then inspect how the theme outputs filter links, canonical tags, pagination, and meta robots. For BigCommerce SEO, the key distinction is whether a filter creates a crawlable category-style URL you can curate, or a parameter state that should remain a shopping aid.
On Shopify, pay close attention to collection handling, app-generated filters, and rendered theme output. Native or app-based filters may create URL variations for color, size, vendor, availability, price, tags, or sort order. A strong setup keeps the collection URL as the primary destination and promotes only selected refinements as intentional landing pages; a weak setup lets every app parameter become an internally linked, crawlable variation.
- Filter URL settings: identify whether the platform or filter app uses clean paths, query parameters, tags, or hash fragments. Query parameters are easier to generate at scale, but they also need tighter crawl and indexation rules.
- Canonical tags: view the rendered HTML, not just the admin setting. The practical question is whether filtered states self-canonicalize, point back to the parent category, or conflict with curated landing pages.
- Robots rules: review what parameter paths are allowed to be crawled before relying on noindex or canonical signals, because blocked URLs may prevent search engines from seeing page-level directives.
- Apps and themes: test the live page after filters load. JavaScript, infinite scroll, and third-party filter apps can expose links that are not obvious from platform settings alone.
Monitor Results and Prevent Filter Problems From Returning
Controls are only finished when the site proves they are holding under real crawling, merchandising, and development activity. Treat the first cleanup as a baseline reset: record how many filter URLs are indexed or discovered, which patterns receive crawler attention, and which approved landing pages earn impressions and clicks. The expected gain is better crawl efficiency and cleaner ranking signals over time, not an immediate rankings rebound.
Use indexability monitoring to separate healthy movement from new index bloat. A good signal is fewer indexed sort, price, availability, and multi-filter URLs while approved category-filter landing pages remain eligible. A weak signal is a rising count of “duplicate,” “alternate canonical,” or unexpected parameter URLs that match filters you meant to suppress.
Crawl stats and log files answer a different question: where search bots are spending requests. Crawl stats show broad movement by response type and file type, while log files show the actual URLs requested. If Googlebot is still hitting thousands of combinations such as ?color=black&size=8&sort=price-desc, the issue may be internal links, app output, sitemap leakage, or rules that allow discovery even after index controls were added.
Canonical reports and rendered-page checks help catch signal conflicts. A strong pattern is consistent: curated landing pages self-canonicalize, low-value variants point to the preferred category when appropriate, and noindex pages remain crawlable long enough for the directive to be seen. A weak pattern is mixed signals, such as a filtered page in the sitemap that canonicals to another URL, or a noindexed page blocked from crawling.
- Weekly: review indexed URL counts by filter pattern, new duplicate clusters, and clicks/impressions for approved landing pages.
- Monthly: compare crawl stats and log files against the baseline to see whether crawl budget is shifting away from low-value filters.
- Before launches: test new filters, apps, themes, category templates, and URL structure changes in a staging or preview environment.
- Seasonally: revisit inventory depth. A filter page with strong products in November may become thin after a sale, while a seasonal collection may deserve temporary promotion.
- After changes: recrawl representative categories, inspect rendered canonicals and meta robots, confirm sitemap inclusion only for approved URLs, and track landing-page performance by page type.
Build Filters for Shoppers Without Letting Them Control Your Index
The operating model is simple: merchandisers can create useful ways to shop, but only approved URL patterns should become search assets. Keep the filter interface generous for users, then put a stricter faceted navigation SEO layer behind it: map the filter universe, decide which combinations deserve landing-page treatment, and prevent everything else from competing with core categories.
That decision should be visible in the site architecture. A strong filter page has a clear query target, enough products, stable inventory, unique copy or metadata, self-canonicalization, internal links, and sitemap inclusion. A weak filter state changes display order, price range, stock status, or a narrow multi-attribute preference; it may help shoppers refine results, but it should not receive the same crawl and index signals as a curated category page.
Use each control for its specific job. Canonical tags point similar URLs toward a preferred version when consolidation is the goal. Noindex keeps user-useful pages out of search results when they should still be crawlable. Robots.txt reduces crawler access to patterns that do not need to be fetched, but it is not an index cleanup tool by itself. Internal links and sitemaps should reinforce the approved set, not expose every possible filter path.
Platforms, apps, themes, and catalogs change, so the rules need ownership. Treat filter SEO like product page optimization: build it into launch checks, merchandising updates, seasonal planning, and technical QA. The final takeaway is straightforward: faceted navigation should support product discovery, while SEO rules decide what search engines crawl, index, and rank.